I’m wondering what training data they are using. The same pirated and scraped data the others are using as well?
They could use self-play and existing ethical models, like Apertus.
That said, they don’t disclose afaict. Haven’t trained it, so they probably don’t know themselves.
Yeah 1 trillion params has to be pretty much all of human written creation
The answer is most probably yes. This is genuinely so tiring.
Will it be open-source or only open-weight ?
Cool! How much does a home server cost that runs it at a reasonable tokens per second?
If you want a more reasonable European developed open-weight model, consider looking at Ministral. Developed by the French, and it’s a slightly smaller version of their Mistral full. Ministral 3 - 27B runs just fine on a 12GB card.
Running EUROPA on in-house hardware would take a lot of memory, even with the usual compression to 4 bits per parameter. At that level, its weights alone would take up at least 476 GB by our math, plus working memory. That puts it in the same range as Muse Spark Open, Meta’s open model. That model has 816 billion parameters and runs on two Apple Mac Studio desktops with 512 GB of memory each.
Although it’s worth noting they haven’t actually trained the thing yet so we’d have to wait to get the actual weights to know more.
Judging from the size of other frontier models on hf, you won’t host it.
The best/biggest you can squeeze on 64gb ram rn is ~70-80B in a Q4 Quant. Going lower with quantization will usually leave you with notable degraded performance.
Is that 64gb vram or ram, cuz if it’s the earlier I guess that’s priced like a cheap car.
Depends on your hardware. Apples unified memory system can give near complete access to the ram for their GPU/npu.
Apart from that you don’t need a single bit of vram/gpu to host a model. Then can be run completely on CPU+ram. But that comes with a significant processing penalty.
On top of that there’s new “engines” which can run a LLM from disk storage +system ram/vram, yet again with lots of speed penalities, since you chunk the model into small pieces and load them into ram accordingly. This will also cripple the lifetime of ssds with the sheer amount of read/write cycles.
Then there’s also dedicated systems or extension cards which can be used as accelerator.
None the less we speak about a minimum of 5000€'s for a system which can run llms and (lightweight) games simultaneously.
VRAM of course
Is 64gb the limit of consumer GPUs at the moment?
You can also get systems with unified memory (from amd for example, or from Apple), which will be available* up to 512gb of ram.
*that means, if you pay the equivalent of a middle sized new car.
Best bang for the buck is a Mac mini with 64gbs memory. But that’s still ~3k€
So like 20k€?
Yes. A 512gb ram Mac Studio costs 25k€
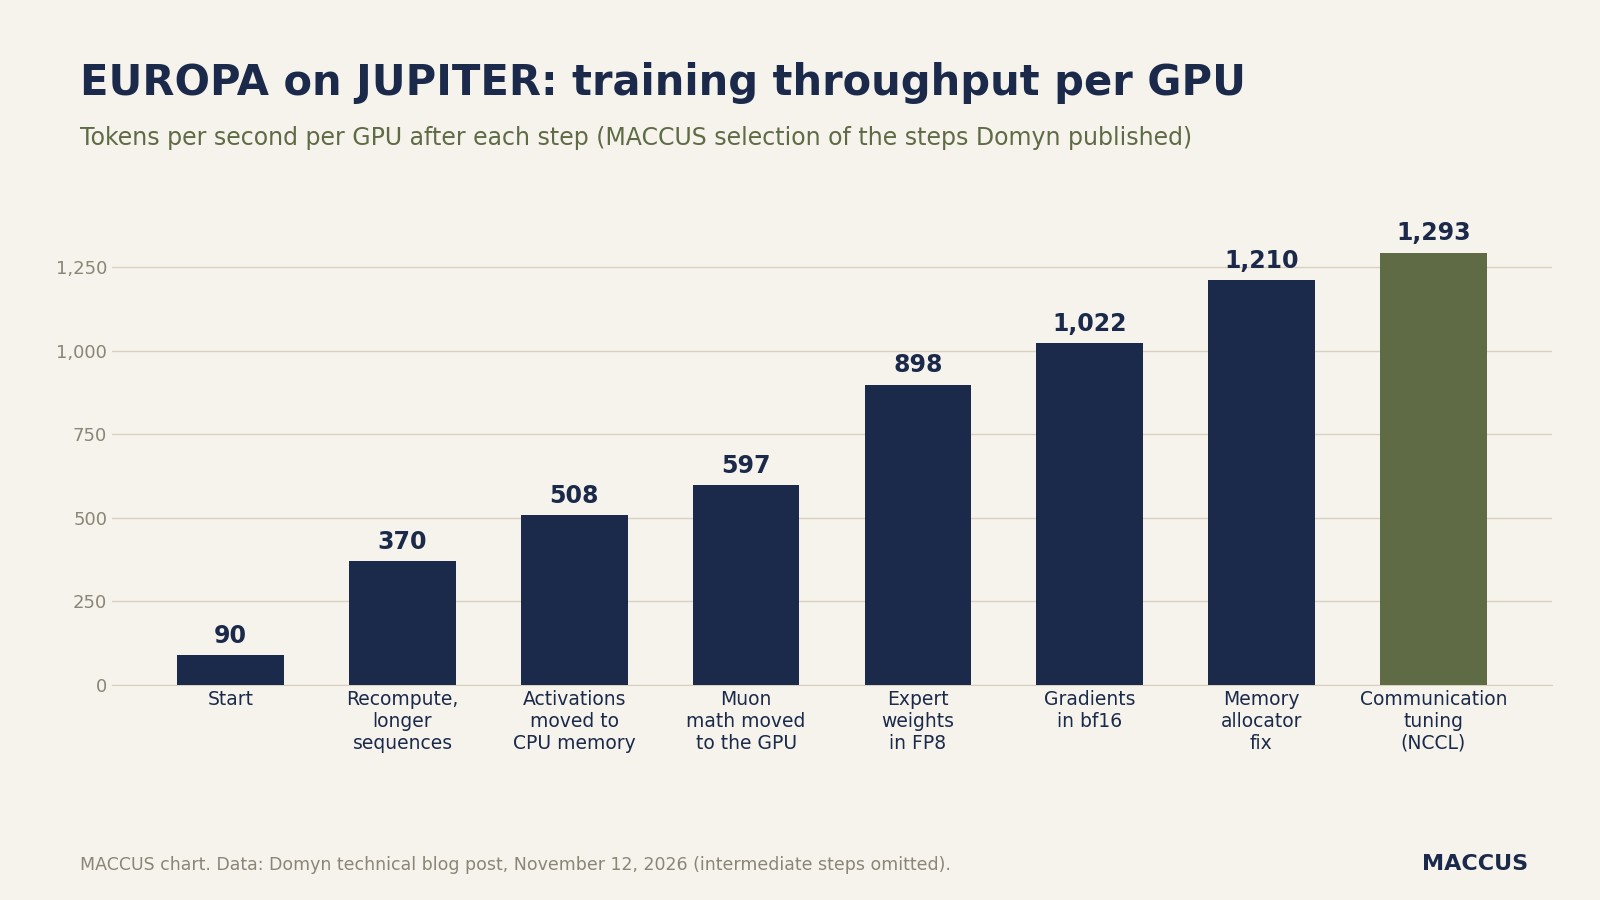
Domyn has not yet released EUROPA’s weights, the files that hold its parameters and let anyone run it on their own hardware. It plans to publish them with details of its training methods when EUROPA comes out. The post gives no date. In June, the outlet Declic Media reported that Domyn was aiming for a release “within the year.”
Guess we’ll have to wait and see